站内导读
中文
定位:FreeToken 是 FlashML 团队开发的边缘原生 MoE 推理引擎,让个人电脑本地运行 290B 以上开源权重模型,面向消费级硬件部署。
核心能力
- 带宽自适应 CPU–GPU 协同执行(q* 策略),配合全层双缓冲 prefill 流式加载与全局 LRU 专家缓存。
- 语义锚点检查点保存循环状态与 KV 缓存,Agent 上下文编辑时跳过重复计算。
- 运行时在专家缓存与 KV 内存间动态重分配显存,无需重启引擎或重载权重。
- 提供 Anthropic/OpenAI 兼容 API,支持 MXFP4、NVFP4、FP8、BF16 量化格式。
适用人群:拥有 RTX 30/40/50 系列显卡的个人开发者,需 Python 环境与 uv 或 pip,通过 CLI 或桌面应用部署模型。
注意:旧 FTW 检查点需按文档修复后才能加载。
日本語
位置づけ:FreeToken は FlashML が開発したエッジ向け Mixture-of-Experts 推論エンジンで、個人向けハードウェア上で 290B 超のオープンウェイトモデルをローカル実行するために設計されています。
主な機能
- 帯域適応型の CPU–GPU 協調実行(q* ポリシー)と全層ダブルバッファ prefill ストリーミング、グローバル LRU エキスパートキャッシュを備えます。
- セマンティックアンカーチェックポイントで再帰状態と KV キャッシュを保存し、Agent のコンテキスト編集時の再計算を省きます。
- 実行中にエキスパートキャッシュと KV メモリ間で VRAM を動的に再配分でき、再起動や重みの再読み込みは不要です。
- Anthropic/OpenAI 互換 API を提供し、MXFP4・NVFP4・FP8・BF16 の量子化形式に対応します。
対象読者:RTX 30/40/50 シリーズ GPU を持つ個人開発者。Python 環境と uv または pip が必要で、CLI かデスクトップアプリから導入します。
注意:旧 FTW チェックポイントはドキュメントに従った修復が必要です。
한국어
정의: FreeToken은 FlashML이 만든 엣지 네이티브 MoE 서빙 엔진으로, 개인용 하드웨어에서 290B 이상의 오픈 웨이트 모델을 로컬로 실행하기 위해 설계되었습니다.
핵심 기능
- 대역폭 적응형 CPU–GPU 협조 실행(q* 정책)과 전체 레이어 더블 버퍼 prefill 스트리밍, 전역 LRU expert 캐시를 제공합니다.
- 시맨틱 앵커 체크포인트로 순환 상태와 KV 캐시를 저장해 Agent 컨텍스트 편집 시 중복 계산을 건너뜁니다.
- 실행 중 expert 캐시와 KV 메모리 사이에서 VRAM을 동적으로 재할당하며, 엔진 재시작이나 가중치 재로딩이 필요 없습니다.
- Anthropic/OpenAI 호환 API를 제공하고 MXFP4, NVFP4, FP8, BF16 양자화 형식을 지원합니다.
대상 사용자: RTX 30/40/50 시리즈 GPU를 보유한 개인 개발자로, Python 환경과 uv 또는 pip가 필요하며 CLI나 데스크톱 앱으로 설치합니다.
주의: 구버전 FTW 체크포인트는 문서에 따라 복구해야 로드됩니다.
English
What it is: FreeToken is an edge-native Mixture-of-Experts serving engine from FlashML, built to run 290B+ open-weight models locally on personal and consumer hardware.
Key capabilities
- Bandwidth-adaptive CPU–GPU co-execution with the q* policy, full-layer double-buffered prefill streaming, and a global LRU expert cache.
- Semantic anchor checkpoints for recurrent state and KV caches, so agentic context edits skip redundant recomputation.
- Dynamic VRAM re-allocation between expert caches and KV memory at runtime, with no engine restart or weight reload.
- Anthropic/OpenAI-compatible APIs and support for MXFP4, NVFP4, FP8, and BF16 quantization formats.
Who it is for: Individual developers with NVIDIA RTX 30/40/50 GPUs, a Python environment, and uv or pip, deploying via CLI or the desktop app.
Caveats: Older FTW checkpoints must be repaired per the docs before loading.
README · 详细文档
来源 · 查看原文

| Download | Paper | Developer Slack | Community Discord | Community WeChat |
Unlock datacenter-class intelligence on the hardware you already own — Run 290B+ frontier MoE models locally on your gaming PC at blistering interactive speeds.
About
FreeToken is an edge-native Mixture-of-Experts (MoE) serving engine designed for running frontier-scale open-weight models on personal and consumer hardware. It treats heterogeneous edge resources—GPUs, CPUs, host memory, and interconnects—as a unified, elastic inference platform. Its core features include:
- Fast Edge-Native Runtime: Provides efficient MoE serving with bandwidth-adaptive CPU–GPU co-execution ($q^\star$ policy), full-layer double-buffered prefill streaming, global LRU expert caching, graph-compatible execution, and the FTW fast weight format.
- Semantic-Aware Caching: Features semantic anchor checkpoints for recurrent state and KV caches, allowing agentic context edits (e.g., tool calls, thinking blocks) to avoid redundant context recomputation.
- Elastic Memory Management: Supports dynamic, runtime VRAM re-allocation between expert caches and KV memory without engine restarts or weight reloading.
- Broad MoE & Ecosystem Support: Supports frontier open-weight MoE models (e.g., DeepSeek-V4-Flash, Qwen3.6-35B-A3B, GLM-5.2) across various parameter scales and quantization formats (e.g., MXFP4, NVFP4, FP8, BF16), with Anthropic/OpenAI-compatible APIs for seamless integration with real-world coding and tool-calling agents (e.g., Codex, Claude Code, OpenCode, OpenClaw, DeepSeek Harness).
- Diverse Consumer Hardware: Scales across consumer laptops, gaming desktops, and workstation GPUs, with native support for NVIDIA RTX 30, RTX 40, and RTX 50 series GPUs.
Getting Started
Desktop app
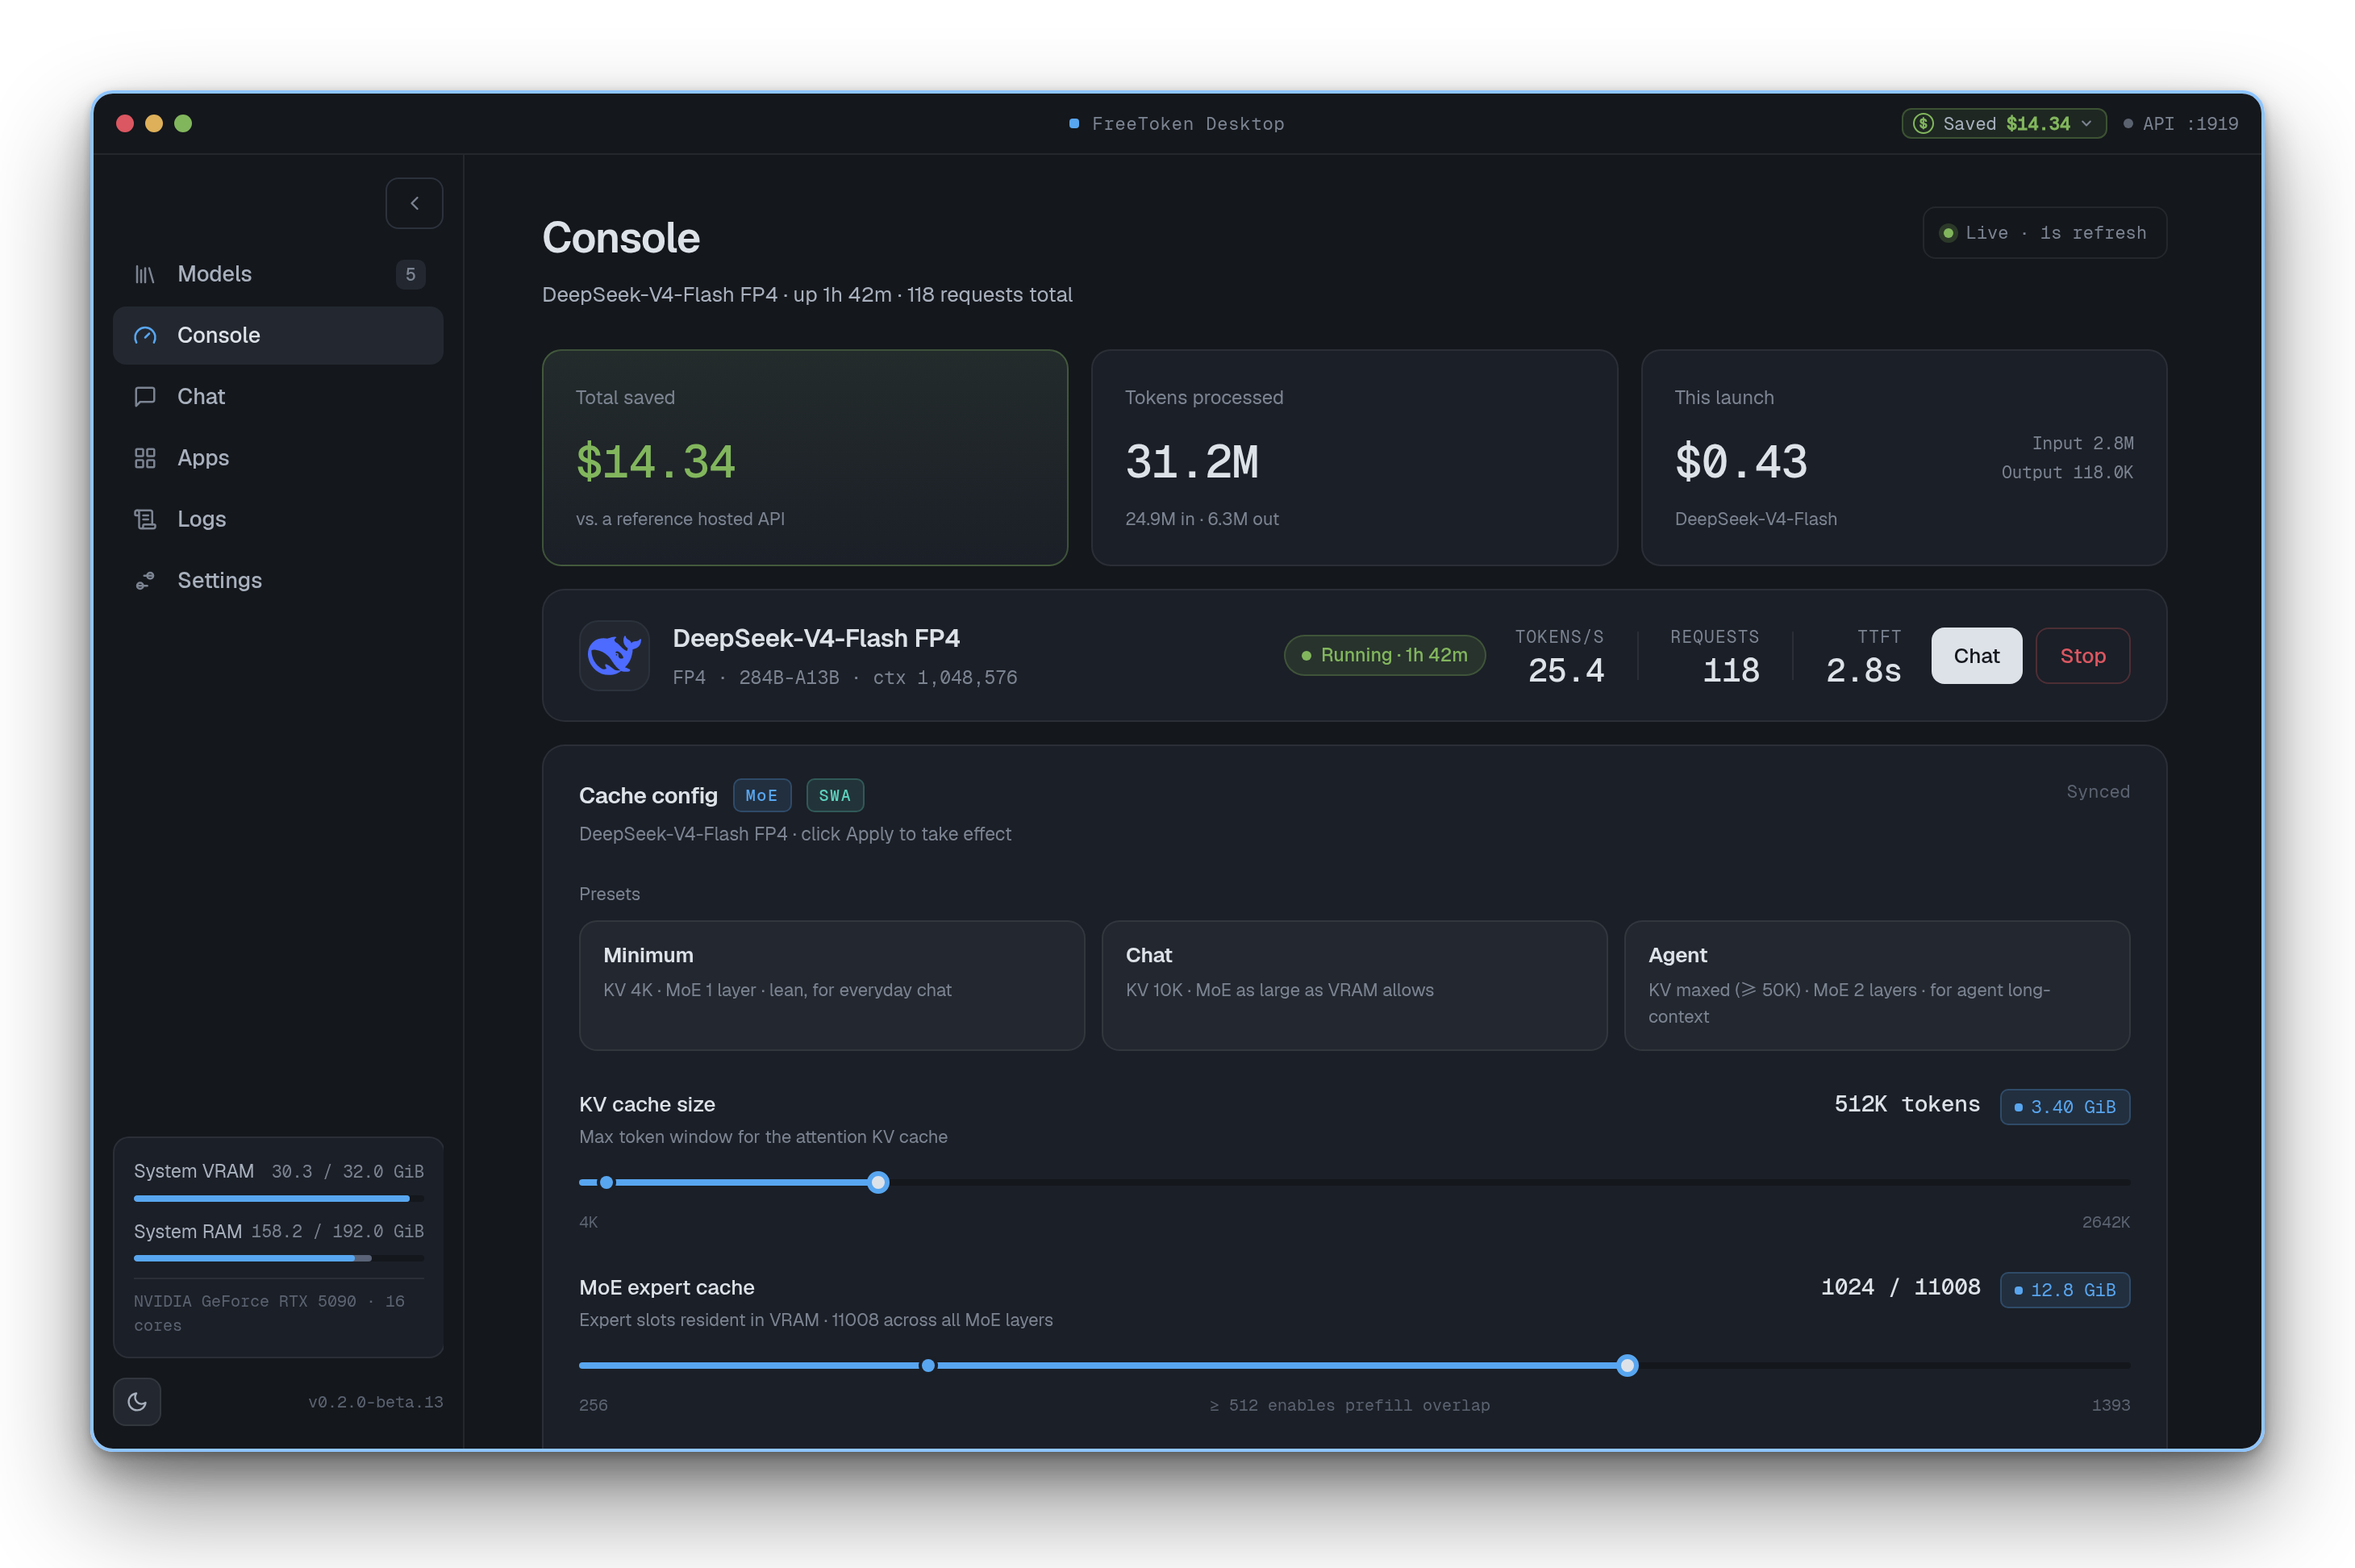
Download FreeToken for Windows or Linux at flashml.ai. It sets the engine up for you and gives you a GUI for running models, chatting, and tuning the engine.
CLI
Install FreeToken with uv (recommended) or pip:
uv pip install "freetoken[accel]"Or build from source:
git clone https://github.com/FlashML-org/FreeToken.git && cd FreeToken
uv venv && source .venv/bin/activate
uv pip install -e ".[accel]"
For More details:
- Install FreeToken
- Quick start
- Supported models
- CLI reference
- Repairing old FTW checkpoints
- Diagnosing a checkpoint that fails to load
Citation
If you use FreeToken for your research, please cite our paper:
@article{yang2026freetoken,
  title={FreeToken: Efficient Edge-Native MoE Serving with Bandwidth-Adaptive Execution},
  author={Yang, Shuo and Fan, Xiaoze and Pan, Melissa and Xi, Haocheng and Wang, Zhe and Sun, Shanlin and Keutzer, Kurt and Han, Song and Zaharia, Matei and Xu, Chenfeng and Stoica, Ion},
  journal={arXiv preprint arXiv:2608.16157},
  year={2026}
}
Acknowledgment
FreeToken was deeply inspired by mini-sglang, and learned the design and reused code from the following projects: SGLang, vLLM, FlashInfer, flash-linear-attention, LightLLM and llama.cpp.