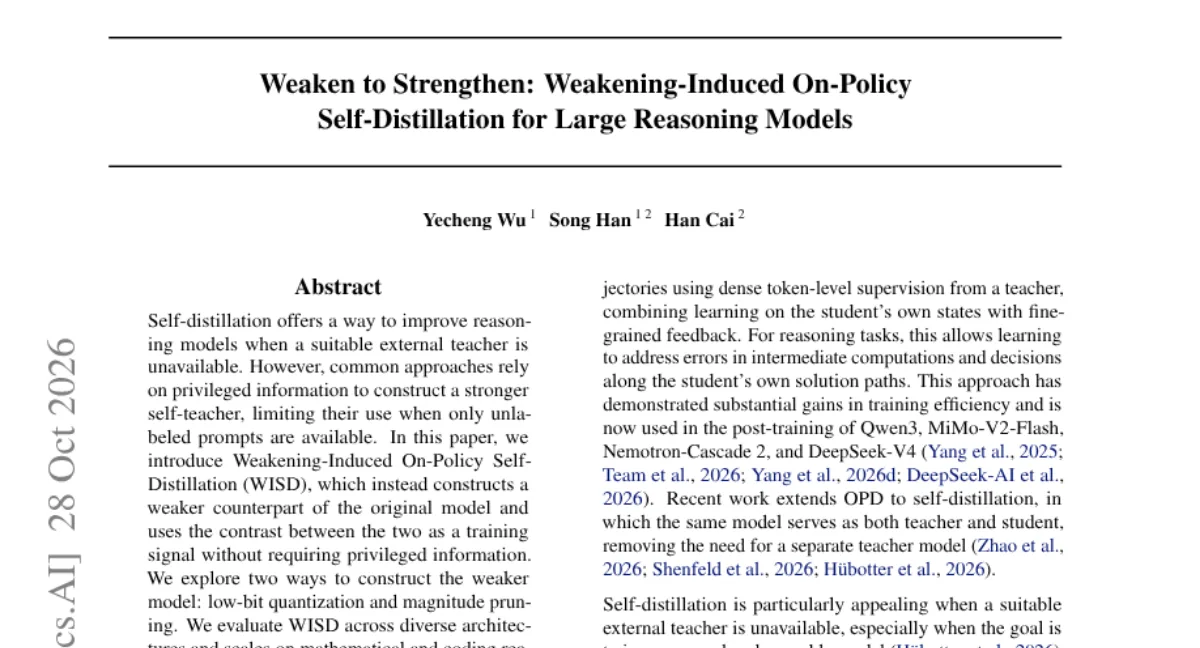
中文 定位:一种面向大型推理模型的自我蒸馏训练方法,由研究者提出,用“先弱化再强化”的思路在无外部教师时提升推理能力。
核心能力
- 不依赖外部教师模型,用模型自身构建蒸馏信号,降低对特权信息的依赖。
- 通过弱化诱导的在线策略自蒸馏,让弱化后的模型充当自我教师。
- 针对推理模型训练场景设计,可与现有 on-policy 蒸馏流程配合。
适用人群:适合做 LLM 推理能力后训练的研究者与工程师,需要具备模型训练与蒸馏流程经验,并能访问模型权重与算力。
注意:README 仅给出方法概述,未列出具体实验配置与代码细节。
日本語 用途:外部教師が使えない状況で、大規模推論モデルの推論能力を自己蒸留によって高めるための手法を解説した内容です。
できること
- 外部教師モデルに頼らず、モデル自身から蒸留信号を構築する。
- 弱化させたモデルを自己教師として使う弱化誘導型のオンライン方針蒸留を採用。
- 推論モデルの訓練に焦点を当て、既存の on-policy 蒸留の流れと組み合わせ可能。
利用場面:LLM の推論能力を事後学習で改善したい研究者やエンジニア向け。モデル重みへのアクセスと訓練環境が必要です。
注意:README は手法の概要のみで、実験設定やコードの詳細は記載されていません。
한국어 용도:외부 교사 모델이 없을 때 대규모 추론 모델의 추론 능력을 자기 증류로 향상시키는 방법을 설명한 내용입니다.
할 수 있는 것
- 외부 교사 모델 없이 모델 자체에서 증류 신호를 구성한다.
- 약화시킨 모델을 자기 교사로 쓰는 약화 유도 온라인 정책 자기 증류를 적용한다.
- 추론 모델 학습에 초점을 두며 기존 on-policy 증류 흐름과 결합할 수 있다.
적용 상황:LLM 추론 능력을 사후 학습으로 개선하려는 연구자와 엔지니어에게 적합합니다. 모델 가중치 접근과 학습 환경이 필요합니다.
주의:README는 방법 개요만 제공하며 실험 설정과 코드 세부 사항은 없습니다.
English What it is: A self-distillation training approach for large reasoning models that weakens the model first, then uses the weakened version as a self-teacher to improve reasoning without an external teacher.
Key capabilities
- Builds distillation signals from the model itself instead of relying on an external teacher.
- Uses weakening-induced on-policy self-distillation, where a weakened model acts as the self-teacher.
- Targets reasoning model training and can fit into existing on-policy distillation pipelines.
Who it is for: Researchers and engineers working on post-training for LLM reasoning, with experience in distillation and access to model weights and compute.
Caveats: The README only outlines the method; experiment setup and code details are not included.